Use cases
See how different teams use SREYUN products to solve operations, security and AI cost problems.
 AIOps
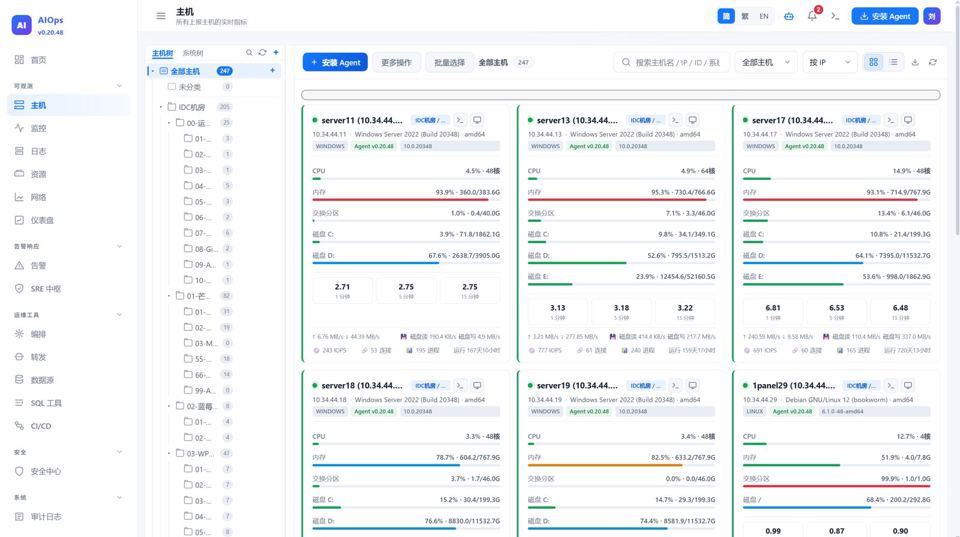
Hybrid cloud and domestic stacks: unified host monitoring and remote ops without inbound ports
Manage physical servers, VMs, containers and cloud hosts in one self-hosted platform, with a remote terminal and desktop over the agent's reverse connection and no inbound ports.
 AIOps
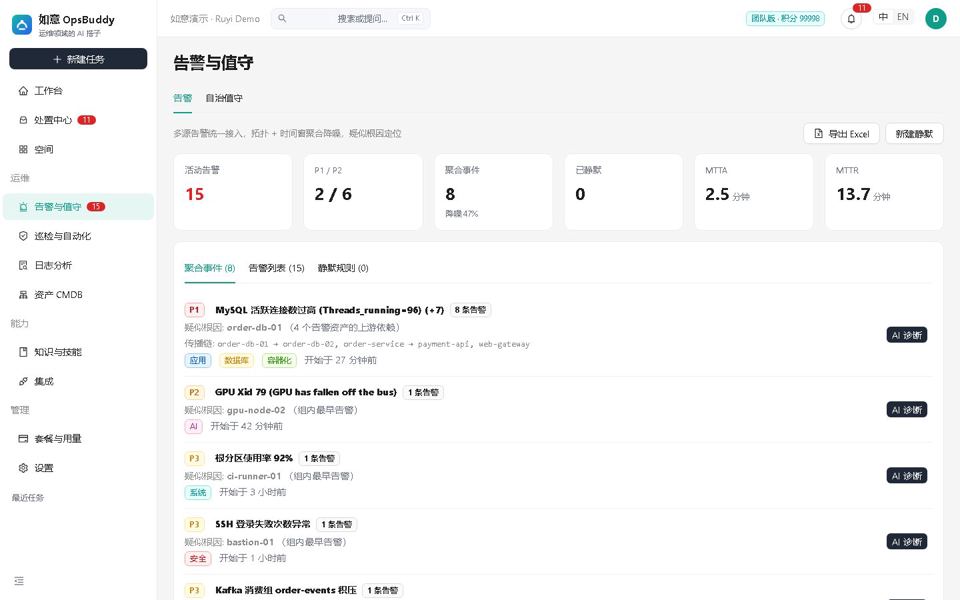
From alert to self-healing: building 24/7 AI on-call
AI groups incoming alerts and analyzes the root cause first, then acts by risk level with approval and self-healing, and verifies the result; on-call engineers only confirm and decide.
 Security operations
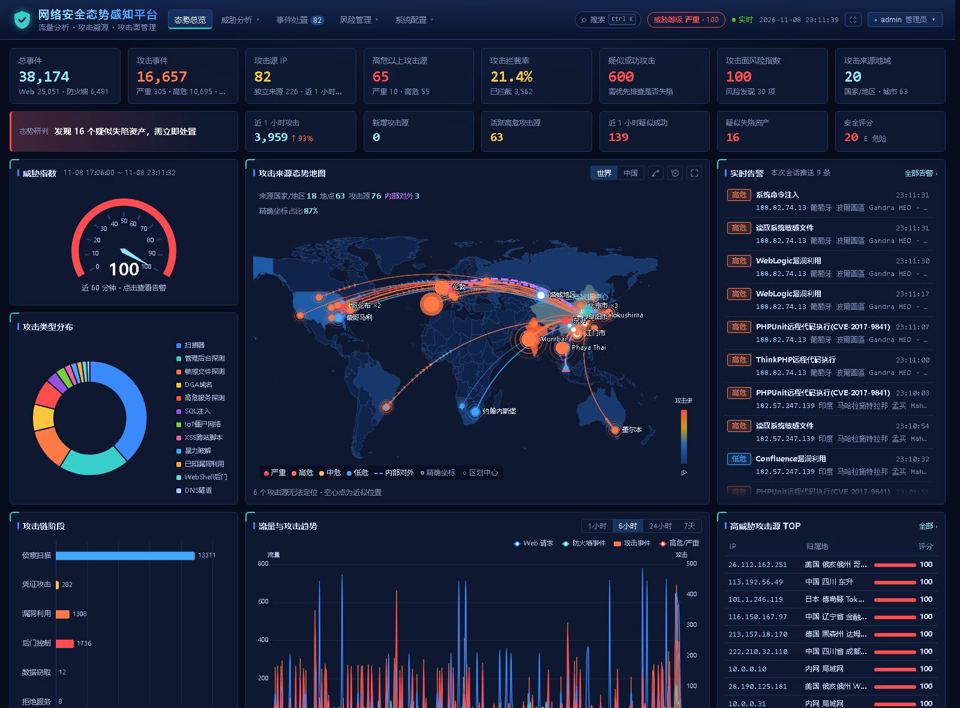
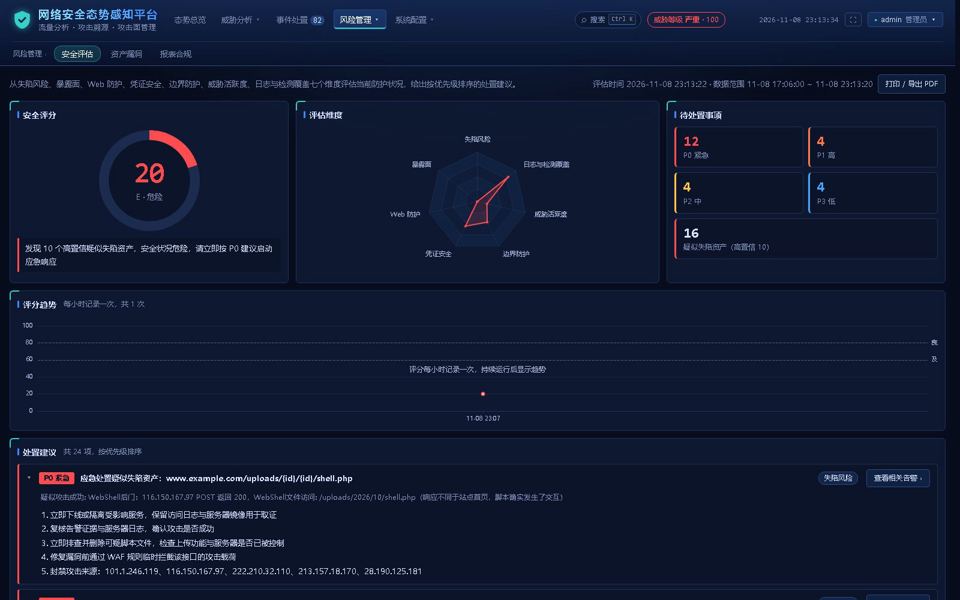
Understand and act on your security posture without a dedicated SOC
A single binary reads the nginx, firewall, host and DNS logs you already have, detects their formats, reviews the evidence and condenses lots of alerts into one list you can act on.
 Security operations
MLPS 2.0 compliance: log retention, audit and self-checks
Raw logs are compressed hourly and protected by a hash chain; together with audit, weekly and monthly reports and an MLPS 2.0 self-check, this meets the log and audit requirements while staying useful day to day.
 AI infrastructure
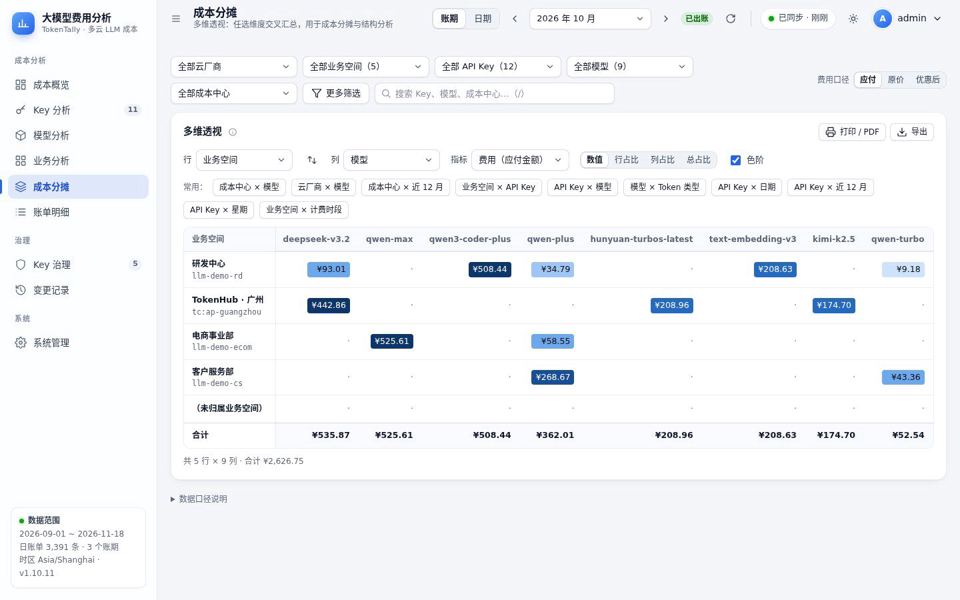
LLM API cost allocation and budget control
Bring the API keys spread over several Alibaba Cloud Model Studio and Tencent Cloud TokenHub accounts together, allocate costs to departments, set budgets and hear about cost anomalies the same day.
 AI infrastructure
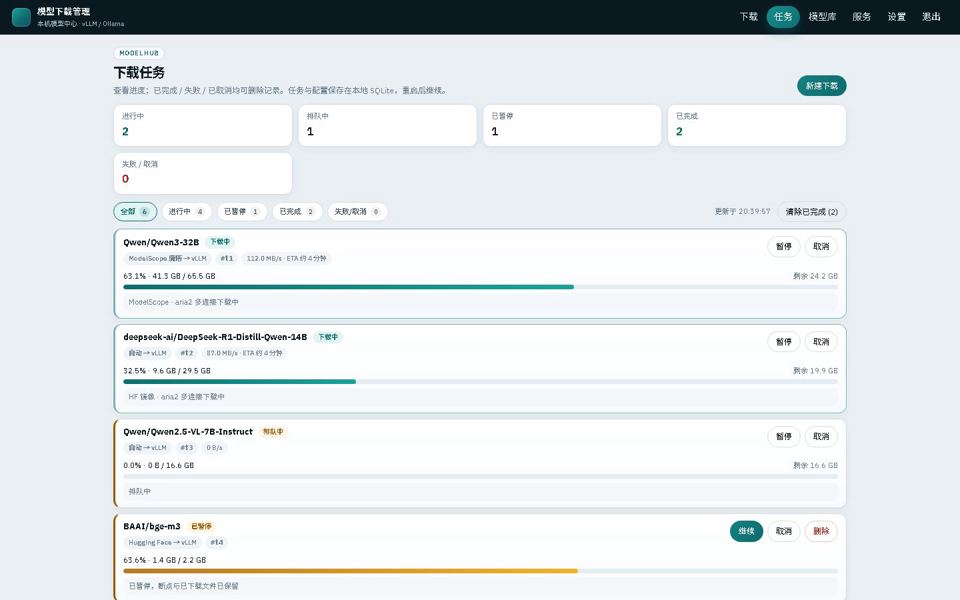
Distributing LLM weights and launching inference on private GPU clusters
Reliably pull ModelScope / Hugging Face weights on network-restricted GPU servers, resume after disconnects, verify and store them, then hand them straight to vLLM / Ollama.
Don't see your scenario?
Tell us what you need and where you deploy, and we will suggest the right products and how to roll them out.
Book a demo