New The SREYUN website is live: five in-house products and reference pricing Learn more →
dlmodel

dlmodel

Self-hosted LLM model weight download manager

On restricted networks, dlmodel reliably pulls ModelScope / Hugging Face models with multi-source fallback and aria2 multi-connection downloads, saved in the vLLM layout; a web UI manages the queue, resume points and pause/resume, and finished models plug into vLLM / Ollama in one click.

dlmodel screenshot

Key features

8 key capabilities of dlmodel at a glance

01

Automatic multi-source fallback

Tries ModelScope first, then falls back to an HF mirror; within each source it steps down from aria2 multi-connection to resumable HTTP to the native SDK, no proxy needed

02

Pause / resume / resumable downloads

Pausing is a first-class state: it stops the network stream safely and keeps the task, progress, downloaded files and resume points, then continues on resume

03

Download queue

Concurrent tasks (1–8) and multiple connections per file, with live progress, speed and ETA; unknown total sizes are labeled clearly and transient network errors retry with exponential backoff

04

Integrity checks

LFS files are checked against the SHA-256 recorded in the repository after download; mismatches are deleted and reported

05

Graceful restarts

Queued and running tasks are saved on shutdown and requeued on the next start, so upgrades and restarts lose nothing

06

Inference integration

Compose profiles start Ollama / vLLM in one step; generate vLLM start commands from downloaded models, scan the model library and pull from Ollama

07

Notifications

DingTalk, Feishu and WeCom group bots, toggled per start / finish / failure / cancel event, with an allow list for outbound addresses

08

Secure and dependency-free

Bearer token authentication (weak tokens refuse to start, failed sign-ins are rate-limited), SQLite (WAL) storage, no database, message queue or frontend build chain

What it is

The first step of self-hosting an LLM often gets stuck on downloading the weights: huge files, restricted networks, dropped connections, several models in line. dlmodel makes this a reliable, visible and resumable local model hub, and hands finished models straight to vLLM or Ollama.

Screenshots
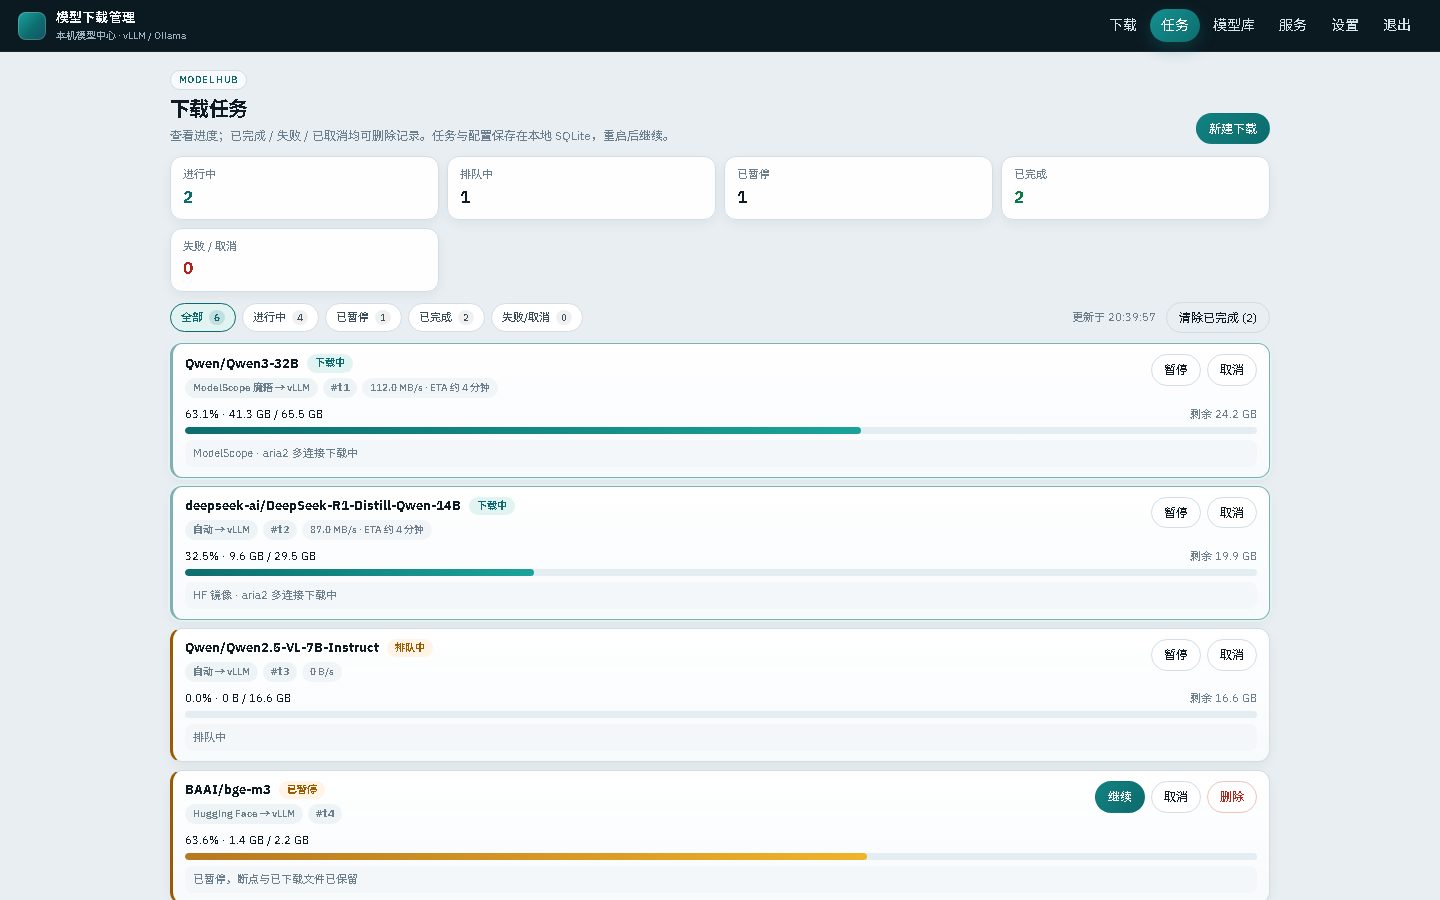
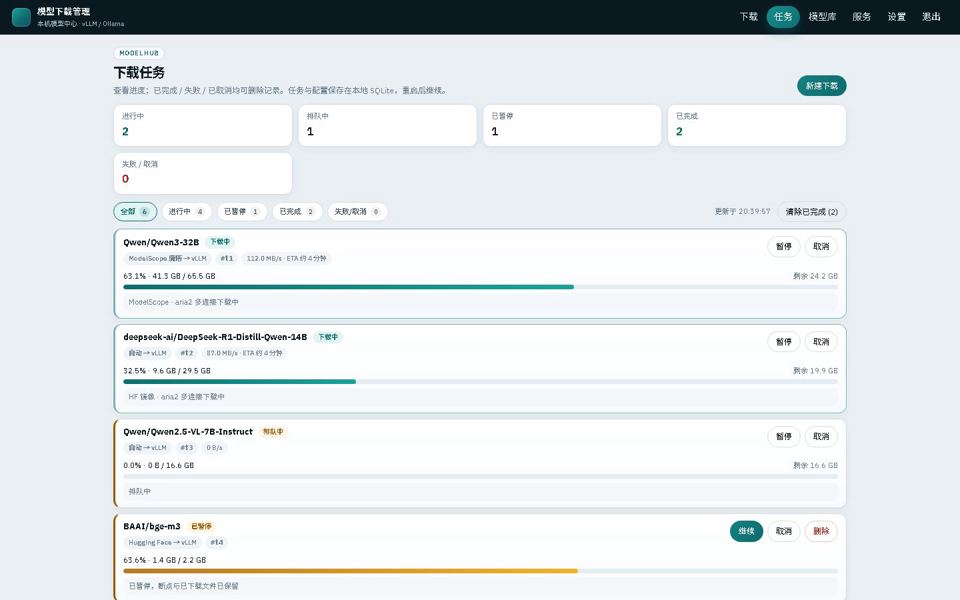
Downloads: concurrent tasks with progress, speed, ETA and pause / resume
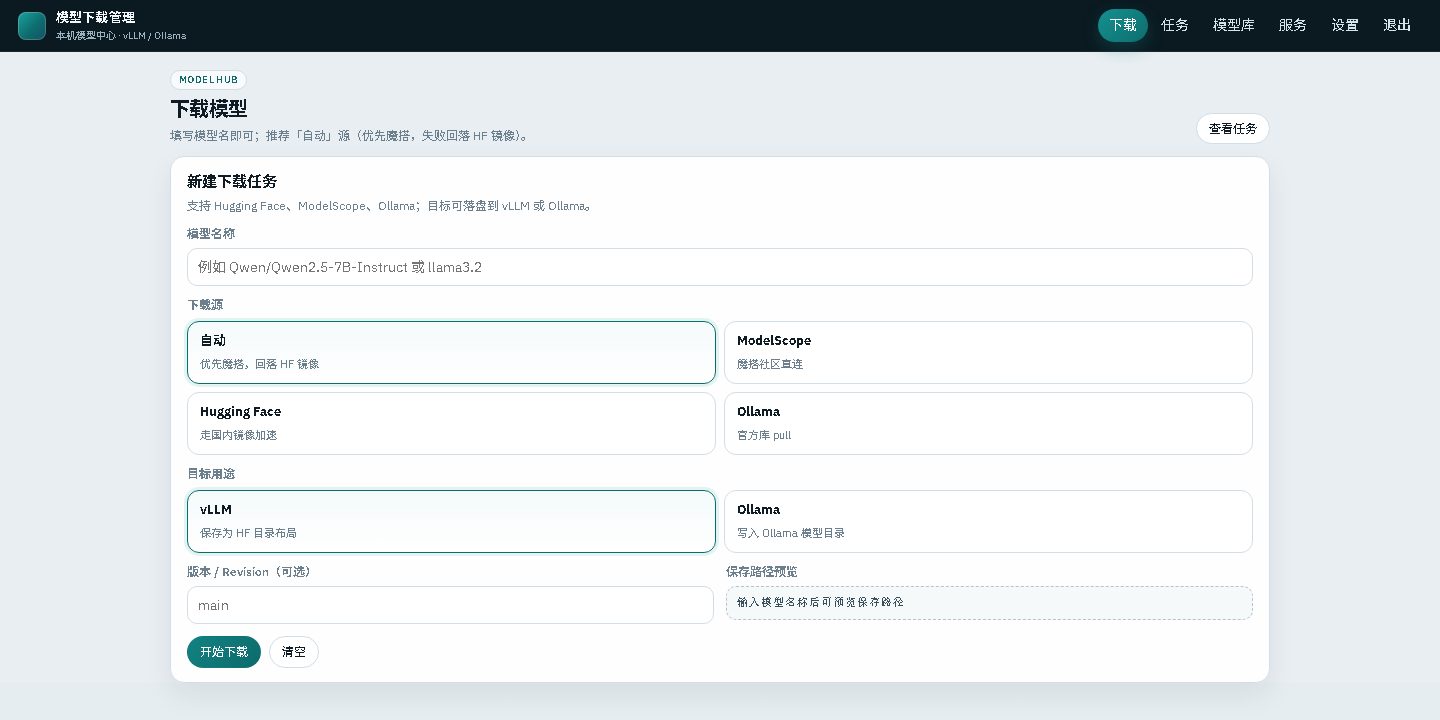
New download: auto / ModelScope / Hugging Face / Ollama sources, saved in the vLLM or Ollama layout

The screenshots use sample tasks.

How it works

  • Downloader: source auto → ModelScope ⇁ HF mirror; within each source aria2 → HTTP Range → SDK.
  • Queue: an asyncio worker pool with the states queued → running → completed / failed / cancelled; pause and resume can interleave at any moment and only one of them takes effect.
  • Storage: the vLLM / HF layout goes to {MODEL_ROOT}/hf/<org>/<repo>/ and Ollama to {MODEL_ROOT}/ollama, shared with the inference services.

Use cases

GPU servers on private networks

Connect to hf-mirror.com and ModelScope without a proxy, resume after disconnects, and get the full weights in one go

Preparing many models

Queue several models and versions, adjust concurrency while running, and get a group message when they finish

Model hub for inference

Share the model volume with vLLM / Ollama; the model library shows disk use, copies paths and generates start commands

Deployment

git clone https://github.com/sreyun/dlmodel.git && cd dlmodel
cp .env.example .env              # set a long random ADMIN_TOKEN
docker compose up -d              # open http://SERVER_IP:8080 and sign in with ADMIN_TOKEN
docker compose --profile ollama up -d   # optional: start Ollama too
docker compose --profile vllm up -d     # optional: start vLLM (needs the NVIDIA Container Toolkit)

The default images are served through Huawei Cloud SWR, so they can be pulled in mainland China without a proxy.

Open-source license

dlmodel is open source under the MIT license. For offline delivery on private networks or help deploying inference services, see pricing.

Need commercial support or a private deployment of dlmodel?

We offer demos, deployment, vendor technical support and custom development to get you running faster.