Open-source, self-hostable
AIOps and security products
Five self-hostable products for operations, security and AI infrastructure. Go live with a single binary or one docker compose command, and your data stays on your own network.
 Closed-loop AI diagnosisDetect → investigate → verify
 Evidence reviewRules out “false successes”
Operations and security software built for self-hosting
Your most critical operations and security data should stay in your hands, and good tools should be simple to deploy.
Self-hosted first
Deploy with a single binary or one docker compose command, run offline on private networks, and keep your data on your own network
Open and transparent
Core products are open source under AGPL-3.0, Apache-2.0 and MIT licenses, so the code can be audited and extended
AI-native, not AI-dependent
AI diagnosis, AI triage and ops agents work out of the box; without a configured LLM, heuristic rules and offline engines take over
Five products across operations, security and AI infrastructure
From host monitoring and security posture to LLM costs and model distribution, each product can be deployed on its own or combined with the others.

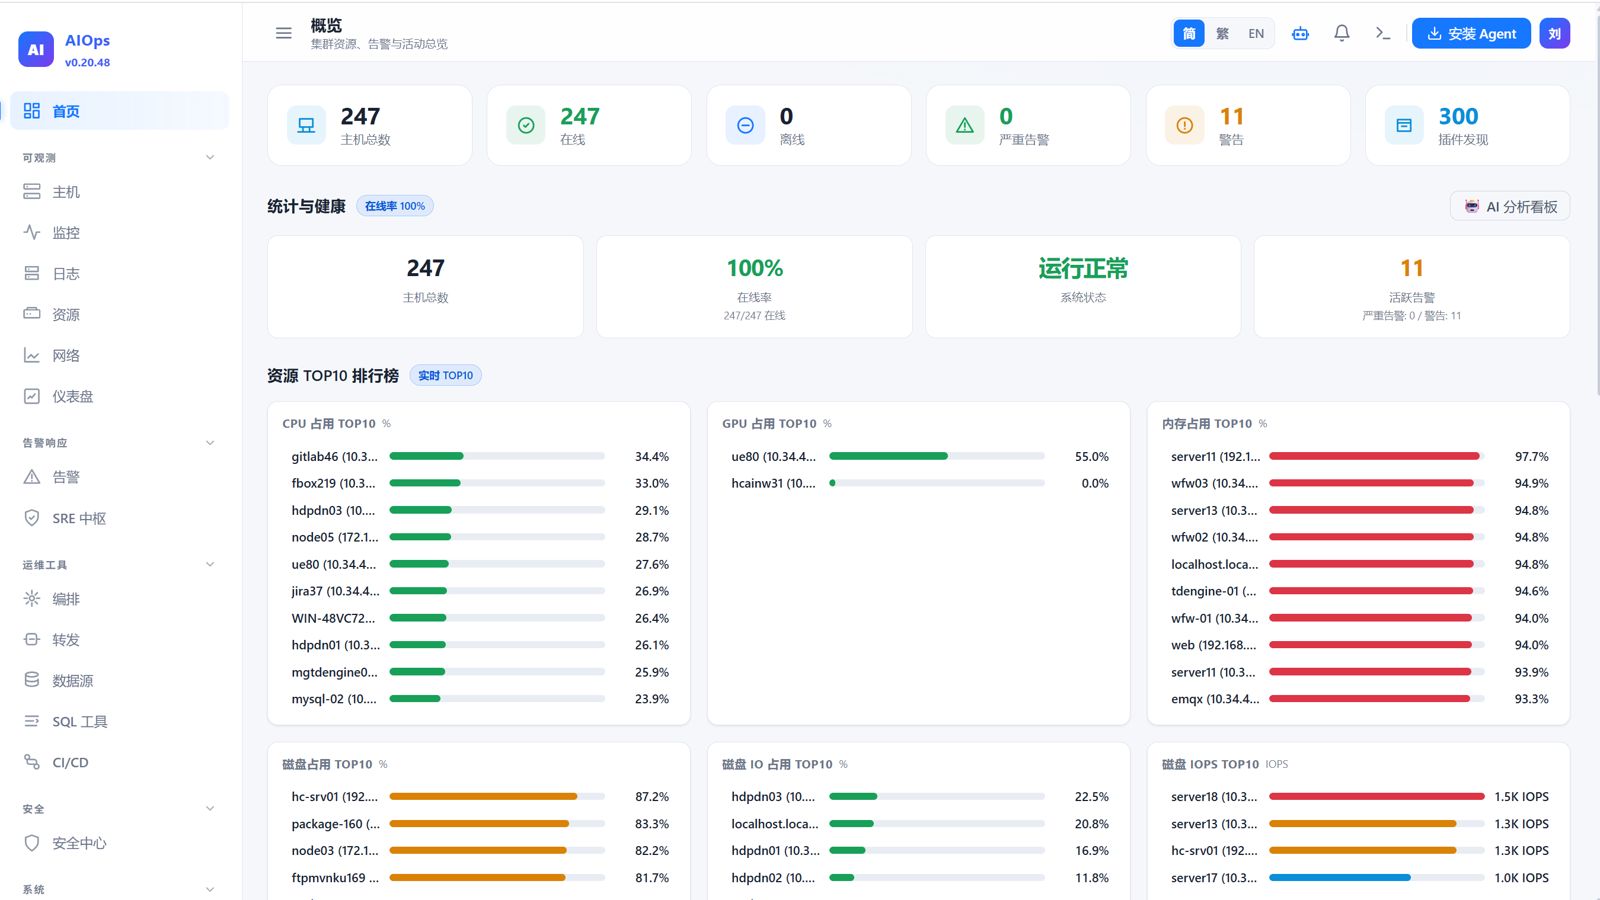
openaiops
Observability, alerting, self-healing, remote operations, Agent OTA and AI diagnosis in one self-hosted platform: one Go server plus one dependency-free agent, live in about 3 minutes with docker compose, and your data stays yours.
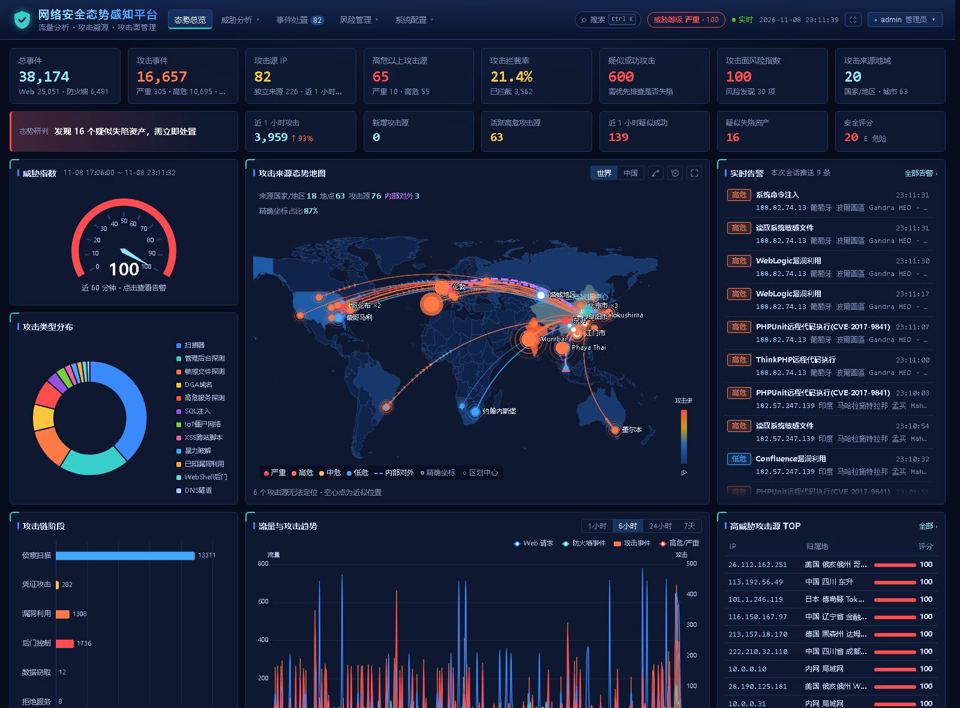
netsa
One binary turns web, firewall / IDS, traffic, host and DNS logs into a security posture you can trace, act on and that corrects itself. No Elasticsearch, Kafka or database needed; works offline on private networks and runs in 5 minutes.
Ruyi OpsBuddy AI
Describe the task in one sentence and OpsBuddy investigates on its own along a diagnosis loop: detect → hypothesize → gather evidence → conclude → act (with approval) → verify automatically → learn. A single Go binary plus PostgreSQL, the same code for SaaS and self-hosting, and it runs offline even without an LLM.

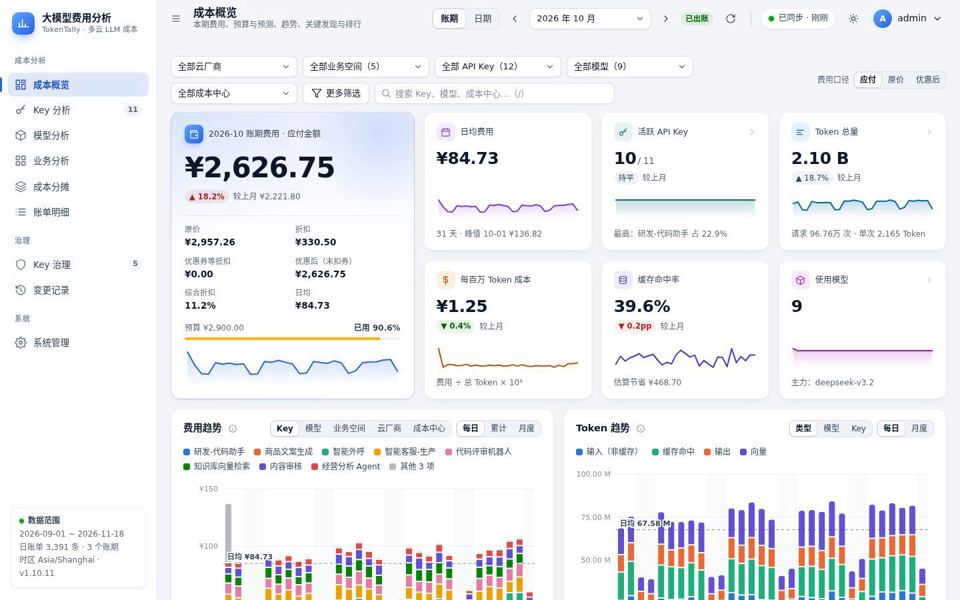
TokenTally
How much does each API key, each model and each department really spend? TokenTally syncs keys and bills from Alibaba Cloud Model Studio and Tencent Cloud TokenHub read-only on a schedule, analyzes them by key, model and cost center, and sends budget overruns and cost anomalies to DingTalk, Feishu, WeCom and email.

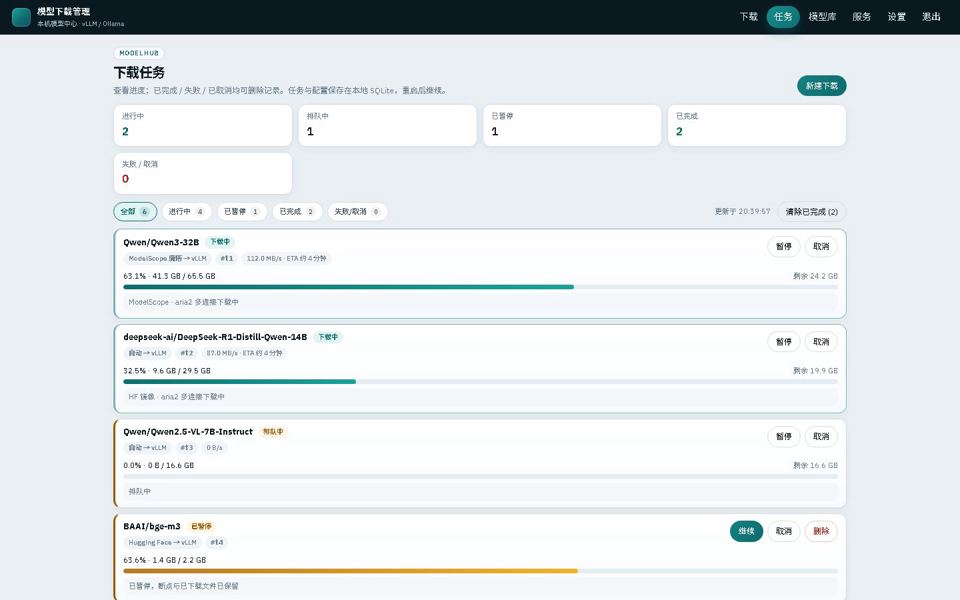
dlmodel
On restricted networks, dlmodel reliably pulls ModelScope / Hugging Face models with multi-source fallback and aria2 multi-connection downloads, saved in the vLLM layout; a web UI manages the queue, resume points and pause/resume, and finished models plug into vLLM / Ollama in one click.
Works with the stack you already run
Native integrations with mainstream monitoring, container, messaging, cloud and LLM ecosystems (see each product's documentation for the exact scope).
Use cases
See how different teams use SREYUN products to solve operations, security and AI cost problems.
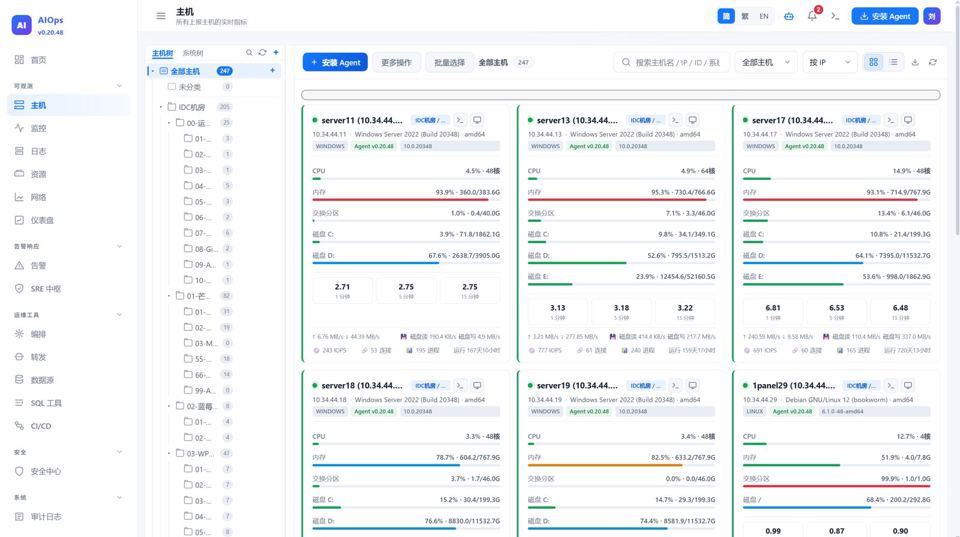 AIOps
Hybrid cloud and domestic stacks: unified host monitoring and remote ops without inbound ports
Manage physical servers, VMs, containers and cloud hosts in one self-hosted platform, with a remote terminal and desktop over the agent's reverse connection and no inbound ports.
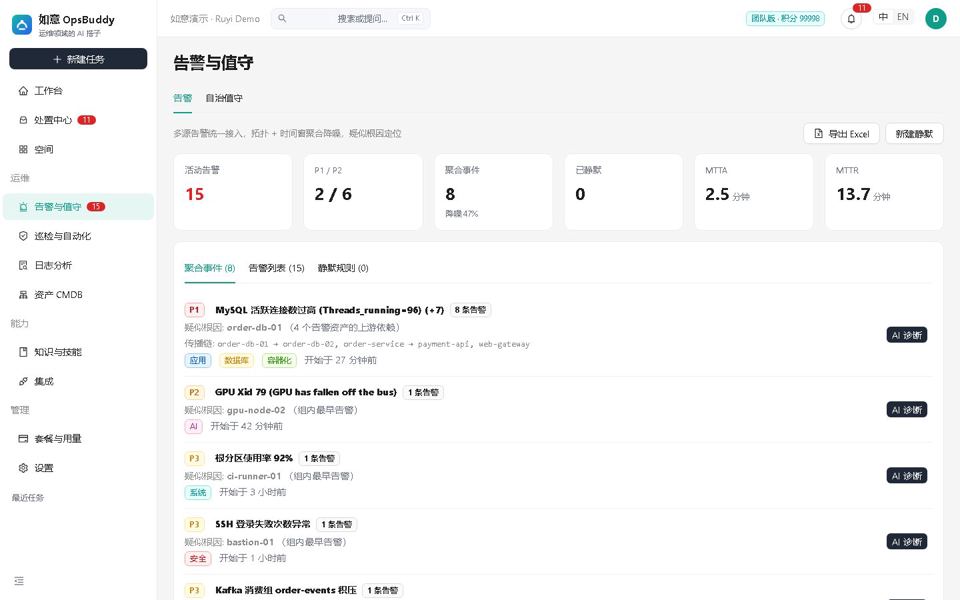 AIOps
From alert to self-healing: building 24/7 AI on-call
AI groups incoming alerts and analyzes the root cause first, then acts by risk level with approval and self-healing, and verifies the result; on-call engineers only confirm and decide.
Security operations
Understand and act on your security posture without a dedicated SOC
A single binary reads the nginx, firewall, host and DNS logs you already have, detects their formats, reviews the evidence and condenses lots of alerts into one list you can act on.
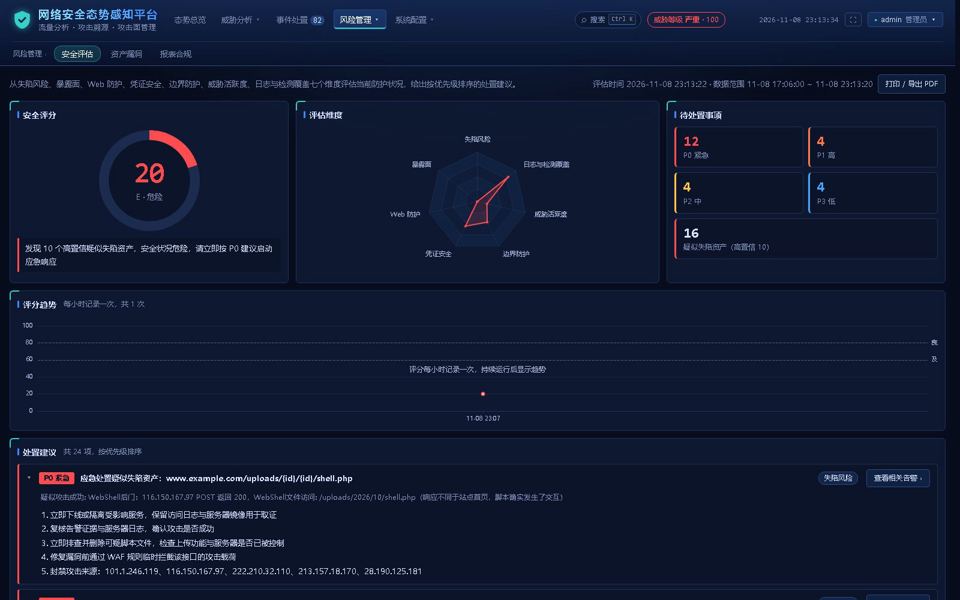 Security operations
MLPS 2.0 compliance: log retention, audit and self-checks
Raw logs are compressed hourly and protected by a hash chain; together with audit, weekly and monthly reports and an MLPS 2.0 self-check, this meets the log and audit requirements while staying useful day to day.
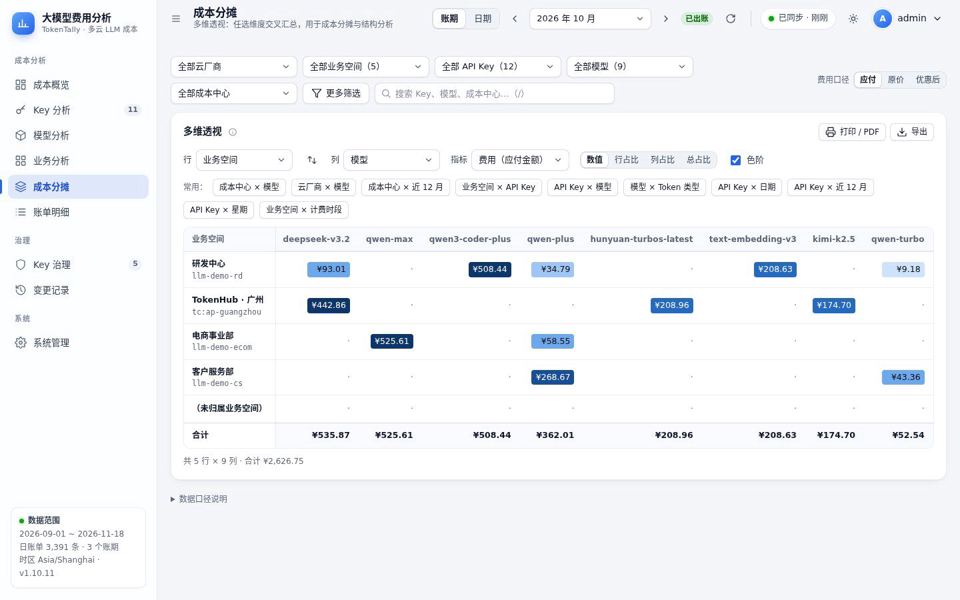 AI infrastructure
LLM API cost allocation and budget control
Bring the API keys spread over several Alibaba Cloud Model Studio and Tencent Cloud TokenHub accounts together, allocate costs to departments, set budgets and hear about cost anomalies the same day.
 AI infrastructure
Distributing LLM weights and launching inference on private GPU clusters
Reliably pull ModelScope / Hugging Face weights on network-restricted GPU servers, resume after disconnects, verify and store them, then hand them straight to vLLM / Ollama.
News
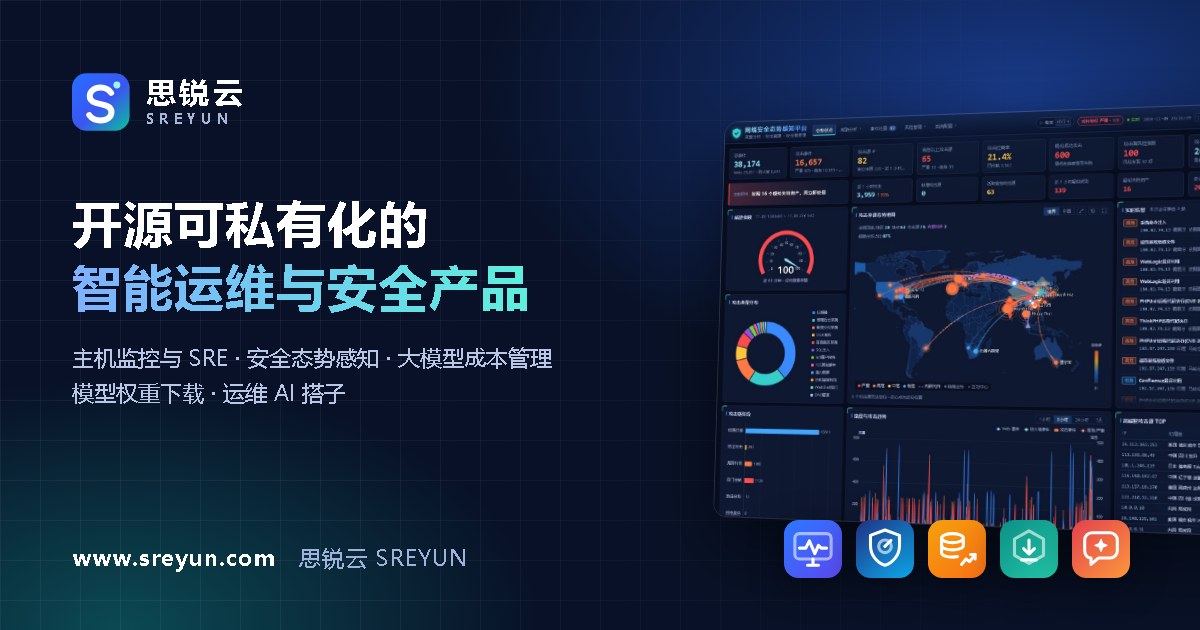
The SREYUN website is live: five in-house products and reference pricing
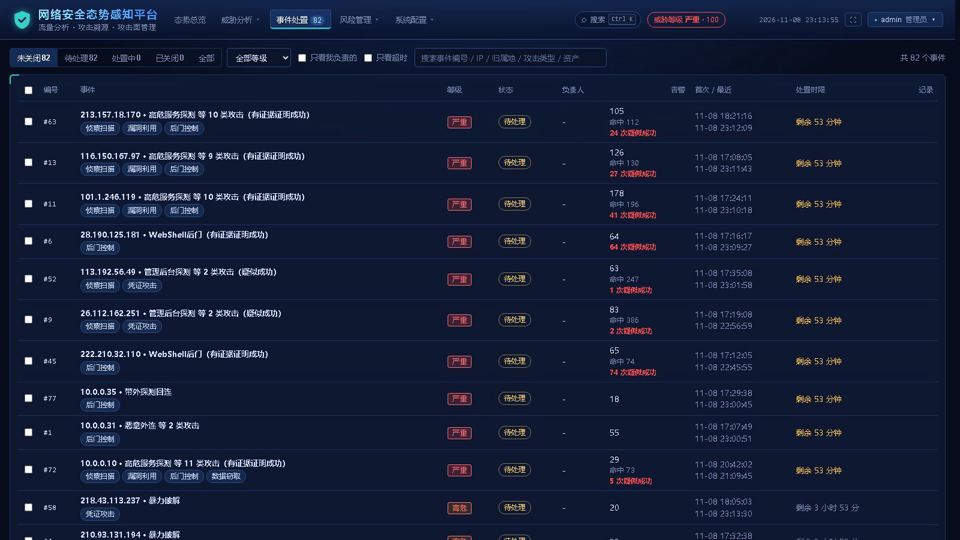
netsa v1.14.2: upgrades and restarts no longer lose logs being processed
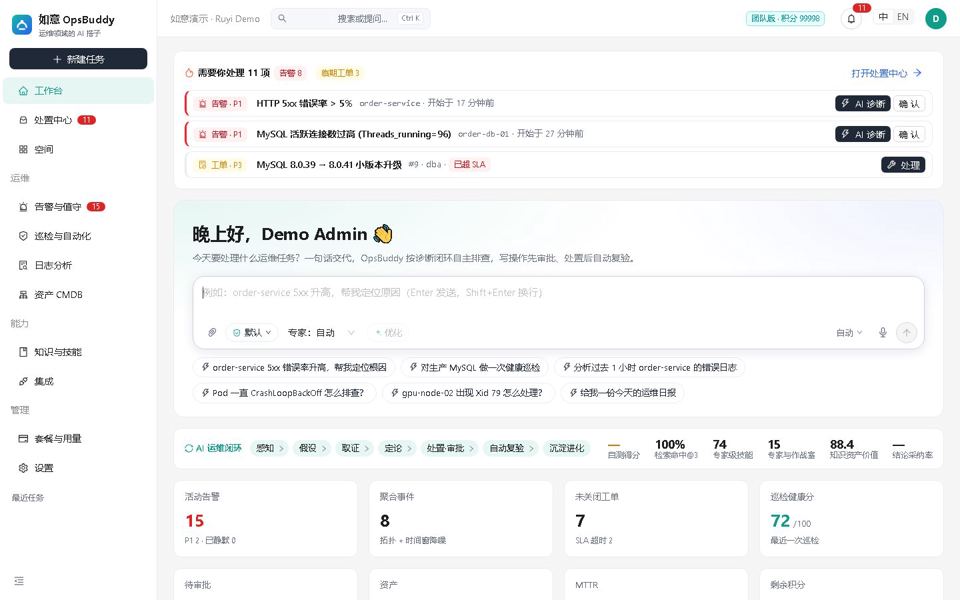
Ruyi OpsBuddy: a seven-stage diagnosis loop that makes AI actually troubleshoot
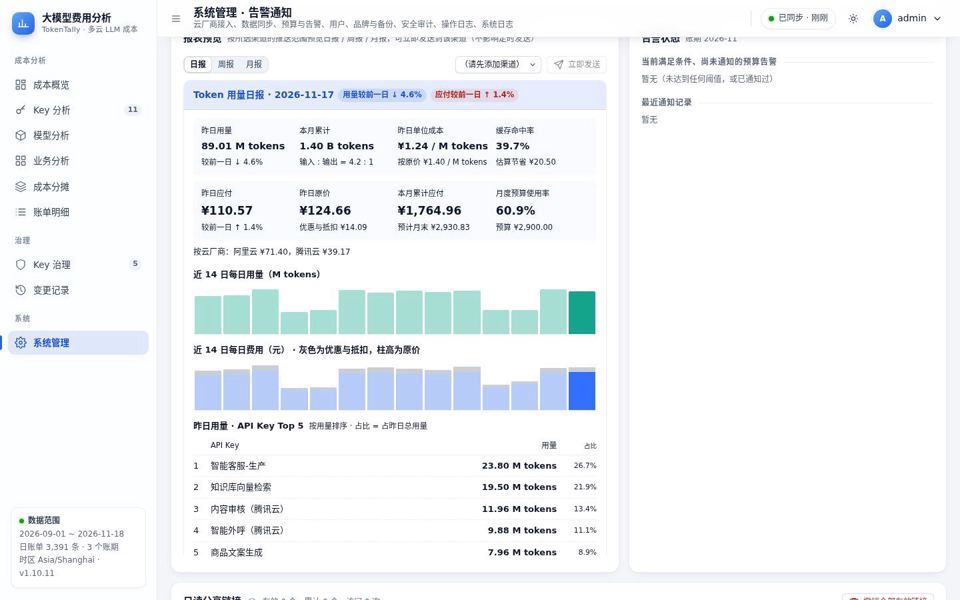
TokenTally reports: usage first, costs second, with a sign-in-free read-only interactive report
Put operations and security back under your control
Tell us about your scenario and we will arrange a product demo, a deployment assessment and a quote.
Book a product demo